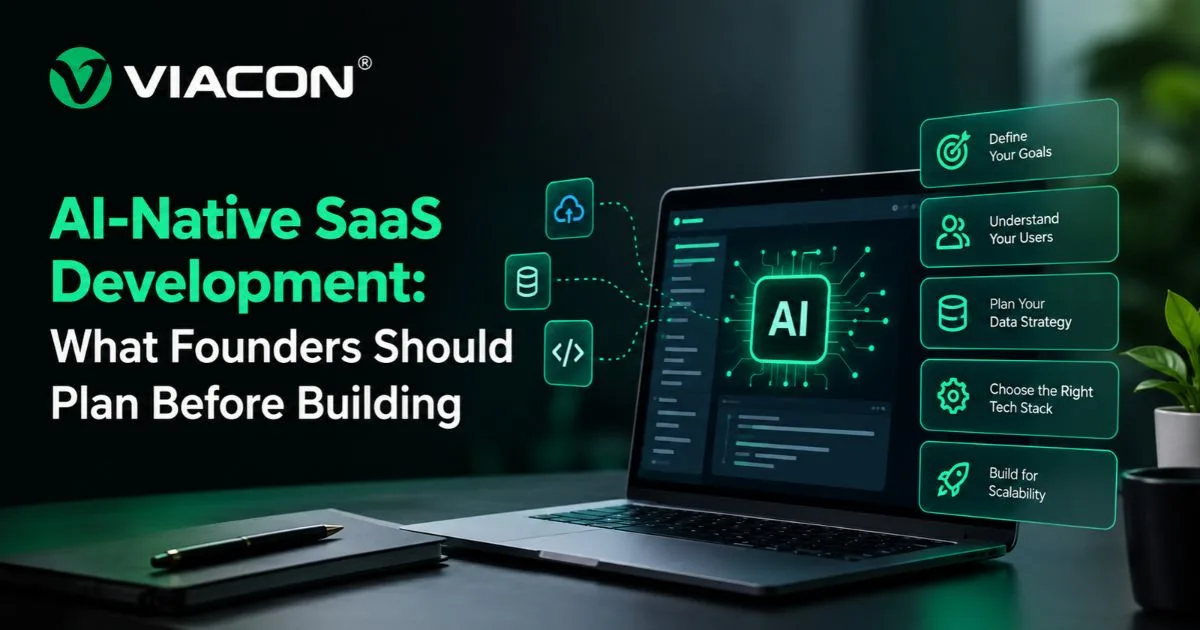
Traditionally, founders treated intelligence in a SaaS product as something added after the core software started working. But the advent of AI has changed that order. Today, the model, data, evaluation system, and user feedback loop often sit inside the product’s basic operating logic.
These changes have made AI SaaS development less predictable than conventional software delivery. A feature can seem functional on the surface, but it can become commercially unviable because of inconsistency, associated costs, and a lack of user trust.
That’s why founders need to resolve several product and operational questions before commissioning a new development.
What Founders Must Review before Commissioning AI SaaS Development
Successful AI SaaS development depends on decisions made before commissioning the first model. That’s why business leaders need a clear idea of the product’s purpose, data requirements, acceptable failure boundaries, and operating costs, because weaknesses in these areas become harder and more expensive to correct after launch.
Start with the Decision and Not with the Model
The first point that founders need to review is what they want to achieve with this new deployment. While the convenient starting point is choosing a model to achieve a certain end goal, i.e.:
- Summarise documents
- Generate marketing copy
- Analyse contracts
- Automate support
But identifying capabilities cannot be equated with product proposition. Instead, a useful starting point is the decision or task this model can improve. And this involves asking:
- Who performs it now?
- What information do they use?
- What happens when they make a mistake?
- How much human review can the workflow support?
Now, consider a SaaS platform designed to help property managers respond to maintenance requests. Here, generating a polite, positive reply is easy, but adding urgency, identifying possible safety risks, assigning the right contractor, or preserving the right audit trail makes it a product problem.
Why? Well, those more complicated tasks require better workflow design, permissions, escalation rules, etc.
At the same time, founders also need to decide whether AI supports judgment or exercises it. A system that can draft recommendations can also tolerate more uncertainty than one that triggers refunds, modifies customer records, or approves applications.
The closer the product moves toward consequential action, the more control, testing, and human oversight it needs.
Choose An Architecture That Can Change
Once the decision part is settled, it's time to choose an architecture. However, the model selection receives undue focus during the selection process, whereas, over time, AI models evolve, and so do their features, cost, and capabilities. Also, each model has its strengths and weaknesses.
That’s why AI software development cannot be a permanent architectural commitment, as it will severely limit the scope of future migration.
Moreover, an AI-native architecture usually needs separation between several layers:
Layer What Founders Should Define Early Common Failure Product workflow User action, expected outcome, and review point Treating the AI response as the complete experience Model layer Provider, routing logic and fallback model Hard-coding one model throughout the application Data layer Sources, permissions, retention and updates Using unverified or poorly governed data Evaluation layer Quality criteria, test cases and failure thresholds Relying on occasional manual checks Operations layer Monitoring, cost controls and incident handling Discovering errors only after customers complainTherefore, implementing a model abstraction layer is important. Because it gives you the room to switch providers or route simple and difficult requests differently. At the same time, it is important to note that abstraction must not become an engineering project of its own.
Treat Data Readiness as a Product Constraint
Business leaders often make a mistake: they think company documents, customer conversations, or transaction histories can provide context to the AI model in use. But in reality, this practice faces hurdles in the form of duplication, contradiction, being outdated, or being subject to other access rules.
The obvious solution here is using retrieval-augmented generation, which can ground a model in selected information. But another challenge remains: this process can't fix weak source material. For instance, if two internal policies don’t align, the application can bring both. Similarly, if permissions are not preserved, one customer can see another’s information.
Data preparation is therefore a critical part of AI application development, not a preliminary administrative task. That’s why before building, teams should map:
- Which sources the application may access
- Who owns and updates each source
- Whether customer data can be sent to an external model
- How deletion and retention requests will be handled
- How retrieved information will be traced in the product
- Which data, if any, may be used for future model improvement
These decisions also affect interface design. A user may need source previews or confidence indicators before acting on an answer. At the same time, if provenance matters, it must be built into the response pipeline rather than appended shortly before launch.
Define Evaluation Before the Demo Looks Impressive
In conventional SaaS development, evaluation heavily relied on deterministic testing. It means checking whether an input produces an expected output, and a failed test signals a defect.
Now, with generative systems, expectations remain the same, and evaluation requires measurable criteria alongside informed human judgment.
Therefore, a useful test set should represent the following:
- Ordinary requests
- Ambiguous inputs
- Adversarial prompts
- Cases where the system ought to refuse or escalate
The criteria will also depend on the product. Here is how: A support assistant could be judged on factual accuracy, policy compliance, and successful resolution. Similarly, a document extraction tool may require field-level precision and a clear mechanism for flagging uncertainty.
Here, business leaders must also define acceptable failure. Because “High-quality responses” cannot be an operational standard. A better requirement might specify that prices must always come from the current catalog, medical questions must be escalated, and unsupported claims must never be presented as company policy.
Additionally, evaluation should also continue after launch. Why? Because user behavior gradually changes the range and nature of inputs. That’s why monitoring only uptime and latency leaves the most important question unanswered: “Is the system still producing useful, defensible results?”
Model the Economics per Completed Task
The last point to review in SaaS application development is the economics of the whole AI operation. Since AI products use variable costs, factors like longer prompts, repeated retries, document retrieval, tool calls, and agent loops can turn an apparently affordable interaction into an expensive one.
The relevant number to focus on here is not the cost of a single model request, but the cost of completing one task. For instance, if one research task can involve eight calls, retrieve several documents, and require a second attempt half the time, all of that affects unit economics.
That’s why the pricing you choose must reflect this uncertainty. Yes, you can choose the unlimited plans, but that can be risky unless you have a clear idea of the usage patterns.
Here you can use credit systems, workload limits, or tiered access. While they are less elegant, they give the business a way to control expenses. Product teams should also decide whether every request deserves the most capable model because routing routine work to a smaller model can protect margins without noticeably reducing user value.
Decide What the First Release Must Prove
To sum up, the end goal of any good AI product development is deciding the objective that you want to achieve with the first release. That’s why start by proving the system can perform a valuable task within an acceptable error boundary. Then determine whether users will trust it, integrate it into their work, and pay enough to support its operating costs.
Once you set these operating boundaries, you can approach an external development team and green-light the project.